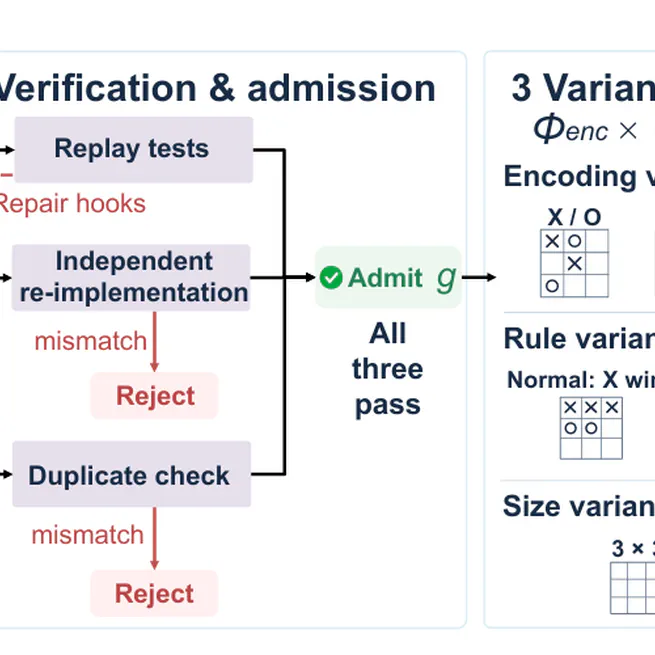
GameSmith: Scaling Zero-Sum Self-Play with Synthesised Games
Citation
10月 10, 2026
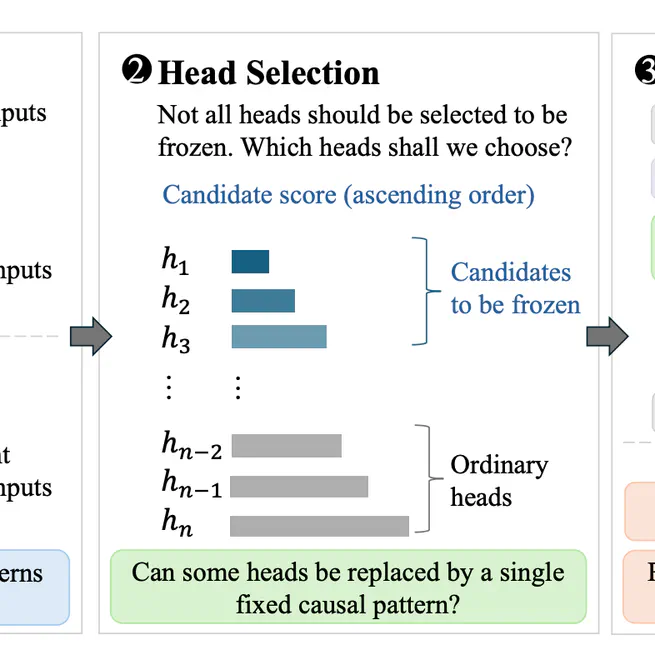
When Can Attention Heads Be Statically Defined?
Citation @misc{li2026attentionheadsstaticallydefined, title={When Can Attention Heads Be Statically Defined?}, author={Weixian Waylon Li and Yintao Tai and Marcio Fonseca and Shay B. Cohen}, year={2026}, eprint={2609.34650}, archivePrefix={arXiv}, primaryClass={cs.LG}, url={https://arxiv.org/abs/2609.34650}, }
9月 25, 2026
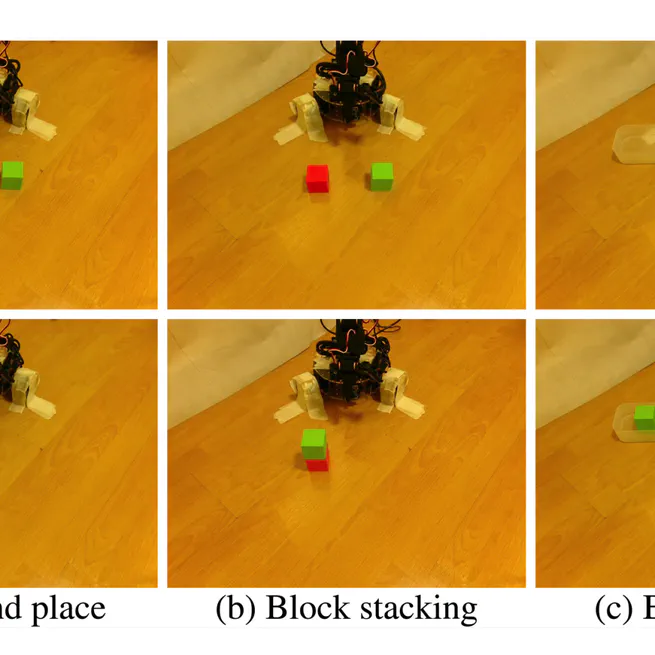
SAVLA: Symmetry-Aware Vision-Language-Action Models for Robotic Manipulation
Citation @misc{li2026savlasymmetryawarevisionlanguageactionmodels, title={SAVLA: Symmetry-Aware Vision-Language-Action Models for Robotic Manipulation}, author={Junle Li and Weixian Waylon Li and Fuxiang Wu and Fusheng Hao and Fengxiang He}, year={2026}, eprint={2609.16641}, archivePrefix={arXiv}, primaryClass={cs.RO}, url={https://arxiv.org/abs/2609.16641}, }
9月 16, 2026
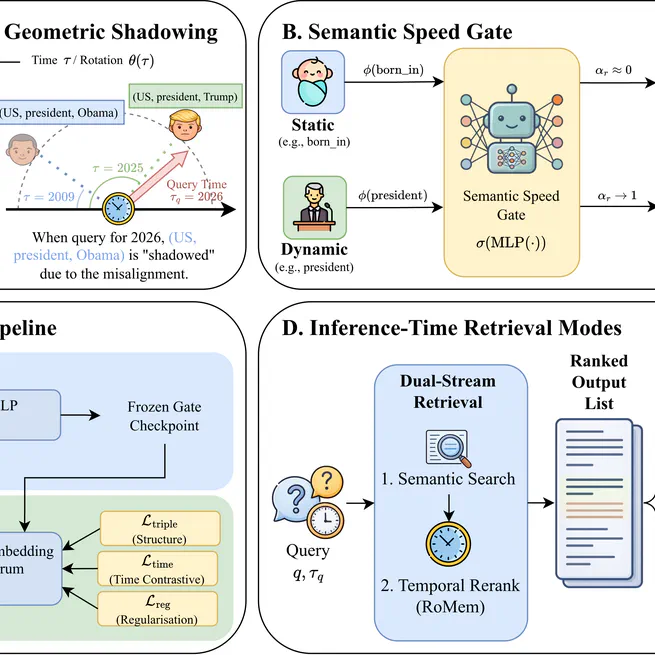
Time is Not a Label: Continuous Phase Rotation for Temporal Knowledge Graphs and Agentic Memory
Citation @misc{li2026timelabelcontinuousphase, title={Time is Not a Label: Continuous Phase Rotation for Temporal Knowledge Graphs and Agentic Memory}, author={Weixian Waylon Li and Jiaxin Zhang and Xianan Jim Yang and Tiejun Ma and Yiwen Guo}, year={2026}, eprint={2604.11544}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2604.11544}, }
8月 22, 2026
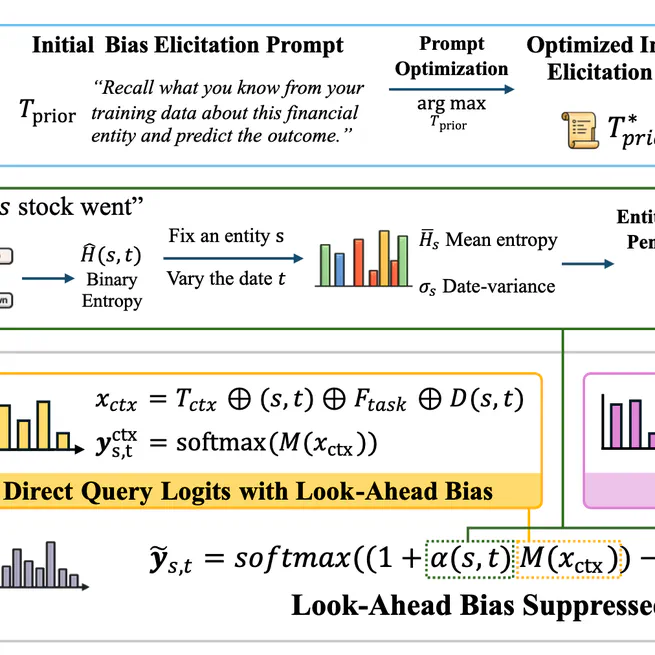
Summoning the Oracle to Slay It: Mitigating Look-Ahead Bias in Financial Backtesting with Large Language Models
Citation @misc{li2026summoningoracleslayit, title={Summoning the Oracle to Slay It: Mitigating Look-Ahead Bias in Financial Backtesting with Large Language Models}, author={Weixian Waylon Li and Mengyu Wang and Tiejun Ma}, year={2026}, eprint={2605.24564}, archivePrefix={arXiv}, primaryClass={cs.AI}, url={https://arxiv.org/abs/2605.24564}, }
5月 26, 2026
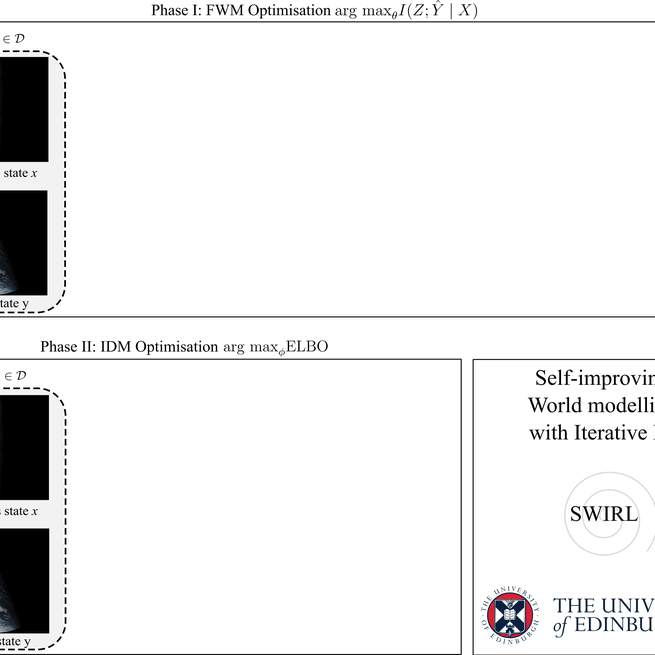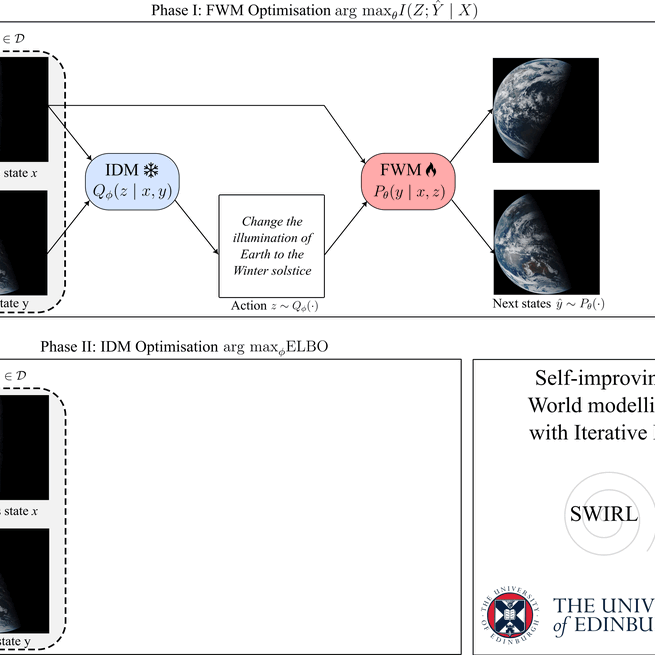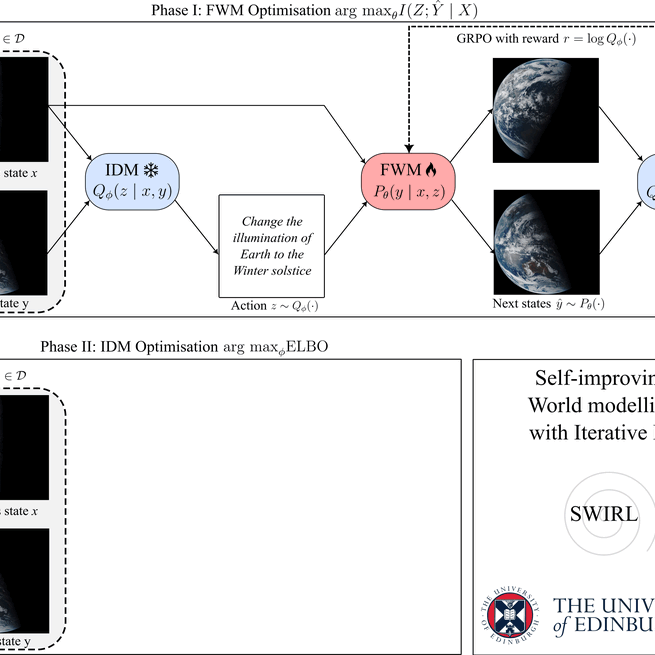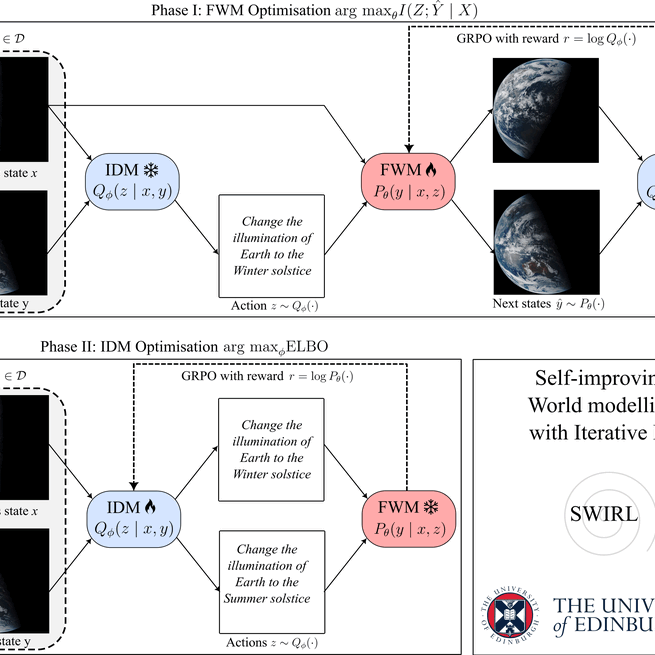
Self-Improving World Modelling with Latent Actions
Citation @misc{qiu2026selfimprovingworldmodellinglatent, title={Self-Improving World Modelling with Latent Actions}, author={Yifu Qiu and Zheng Zhao and Waylon Li and Yftah Ziser and Anna Korhonen and Shay B. Cohen and Edoardo M. Ponti}, year={2026}, eprint={2602.06130}, archivePrefix={arXiv}, primaryClass={cs.LG}, url={https://arxiv.org/abs/2602.06130}, }
2月 9, 2026
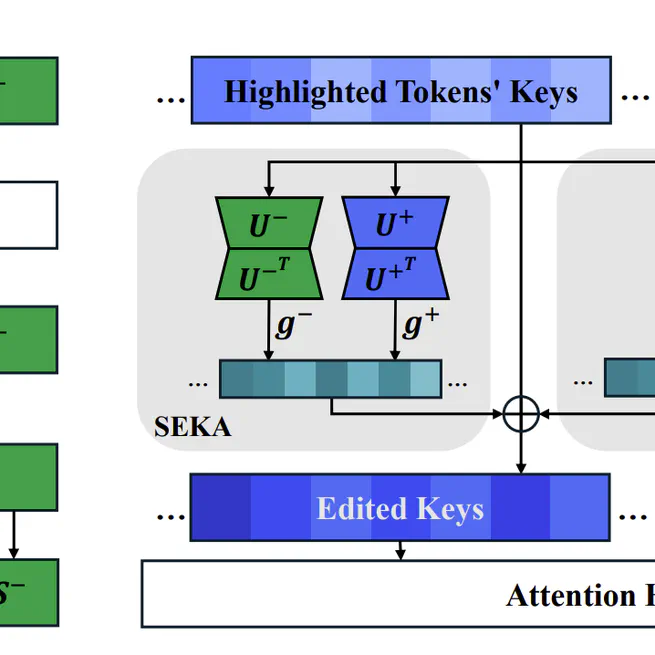
Spectral Attention Steering for Prompt Highlighting
Citation @inproceedings{ li-2026spectral, title={Spectral Attention Steering for Prompt Highlighting}, author={Li, Weixian Waylon and Niu, Yuchen and Yang, Yongxin and Li, Keshuang and Ma, Tiejun and Cohen, Shay B.}, booktitle={The Fourteenth International Conference on Learning Representations}, year={2026}, url={https://openreview.net/forum?id=XfLvGIFmAN} }
1月 27, 2026
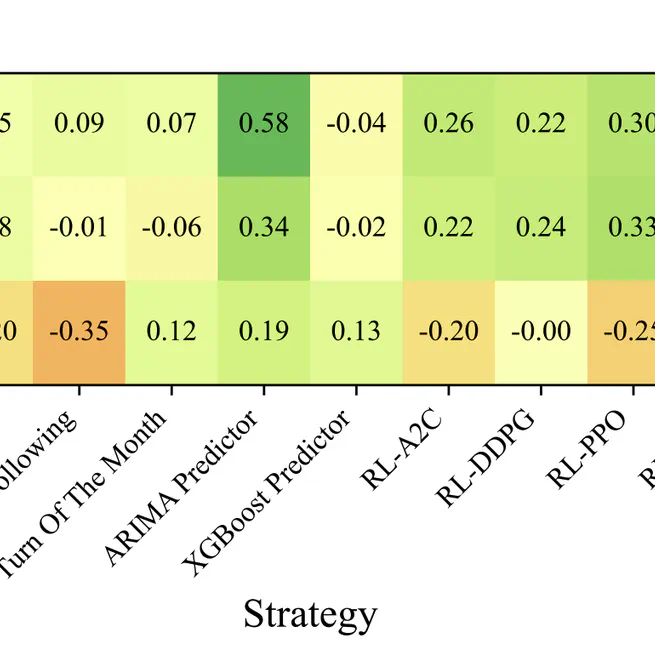
Can LLM-based Financial Investing Strategies Outperform the Market in Long Run?
Citation @inproceedings{10.1145/3770854.3785702, author = {Li, Weixian Waylon and Kim, Hyeonjun and Cucuringu, Mihai and Ma, Tiejun}, title = {Can LLM-based Financial Investing Strategies Outperform the Market in Long Run?}, year = {2026}, isbn = {9798400722585}, publisher = {Association for Computing Machinery}, address = {New York, NY, USA}, url = {https://doi.org/10.1145/3770854.3785702}, doi = {10.1145/3770854.3785702}, abstract = {Large Language Models (LLMs) have recently been leveraged for asset pricing and stock trading applications, enabling AI agents to generate investment decisions from unstructured financial data. However, most evaluations of LLM timing-based investing strategies are conducted on narrow timeframes and limited stock universes, overstating effectiveness due to survivorship and data-snooping biases. We critically assess their generalizability and robustness by proposing FINSABER, a backtesting framework evaluating timing-based strategies across longer periods and a larger universe of symbols. Systematic backtests over two decades and 100+ symbols reveal that previously reported LLM advantages deteriorate significantly under broader cross-section and over a longer-term evaluation. Our market regime analysis further demonstrates that LLM strategies are overly conservative in bull markets, underperforming passive benchmarks, and overly aggressive in bear markets, incurring heavy losses. These findings highlight the need to develop LLM strategies that are able to prioritise trend detection and regime-aware risk controls over mere scaling of framework complexity.}, booktitle = {Proceedings of the 32nd ACM SIGKDD Conference on Knowledge Discovery and Data Mining V.1}, pages = {2711–2722}, numpages = {12}, keywords = {automated trading, llm investors, backtest, benchmark}, location = {Republic of Korea}, series = {KDD '26} }
11月 24, 2025
TSPRank: Bridging Pairwise and Listwise Methods with a Bilinear Travelling Salesman Model
Citation @inproceedings{10.1145/3690624.3709234, author = {Li, Weixian Waylon and Ziser, Yftah and Xie, Yifei and Cohen, Shay B. and Ma, Tiejun}, title = {TSPRank: Bridging Pairwise and Listwise Methods with a Bilinear Travelling Salesman Model}, year = {2025}, isbn = {9798400712456}, publisher = {Association for Computing Machinery}, address = {New York, NY, USA}, url = {https://doi.org/10.1145/3690624.3709234}, doi = {10.1145/3690624.3709234}, abstract = {Traditional Learning-To-Rank (LETOR) approaches, including pairwise methods like RankNet and LambdaMART, often fall short by solely focusing on pairwise comparisons, leading to sub-optimal global rankings. Conversely, deep learning based listwise methods, while aiming to optimise entire lists, require complex tuning and yield only marginal improvements over robust pairwise models. To overcome these limitations, we introduce Travelling Salesman Problem Rank (TSPRank), a hybrid pairwise-listwise ranking method. TSPRank reframes the ranking problem as a Travelling Salesman Problem (TSP), a well-known combinatorial optimisation challenge that has been extensively studied for its numerous solution algorithms and applications. This approach enables the modelling of pairwise relationships and leverages combinatorial optimisation to determine the listwise ranking. TSPRank can be directly integrated as an additional component into embeddings generated by existing backbone models to enhance ranking performance. Our extensive experiments across three backbone models on diverse tasks, including stock ranking, information retrieval, and historical events ordering, demonstrate that TSPRank significantly outperforms both pure pairwise and listwise methods. Our qualitative analysis reveals that TSPRank's main advantage over existing methods is its ability to harness global information better while ranking. TSPRank's robustness and superior performance across different domains highlight its potential as a versatile and effective LETOR solution.}, booktitle = {Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining V.1}, pages = {707–718}, numpages = {12}, keywords = {learning-to-rank, pairwise-listwise ranking, travelling salesman problem}, location = {Toronto ON, Canada}, series = {KDD '25} }
2月 18, 2025
SynthRank: Synthetic Data Generation of Individual’s Financial Transactions Through Learning to Ranking
2月 1, 2024